Benchmarks

My performance testing of Holster so far has come from just working on the applications I want, and then seeing where things feel slow. This has the double pay-off of improving the usability of the apps and improving Holster overall.

I decided to add some benchmark testing though, to get a better sense of where things are at. This was a task Claude was able to set up very quickly, and when I first had some results I wasn't sure what to compare them to. I first looked for existing GunDB performance numbers but knew that benchmarking is notoriously subjective, so decided to add side by side testing in the benchmark itself. Everything is in the repo, so others can try it or at least see the assumptions made to produce the results below. Both Holster and GunDB needed some config tweaks to produce comparable results.

Adding benchmarking showed where a number of performance improvements could be made, so these have also been added to the latest Holster release and are also reflected in the results. The main fix was updating the batch size used when writing to disk back to the same value as GunDB, which was causing disk churn under load. Also a callback timeout was used very often but wasn't required, which is a more noticeable improvement in real applications.

The aim here is to get both Holster and GunDB writing to disk and then checking whether the data can be read back afterwards. It tries to make a fair comparison by reducing GunDB's write delay to 1ms to match Holster, down from its default 250ms delay. I think this delay might have been set to reduce failed writes, but my testing at the default, and at in-between values only reduced the failures, it didn't account for them completely.

Setup

  • Holster 3.0.0 and Gun 0.2020.1241.

  • Node v22.22.1 on an Intel Core Ultra X7 358H, writing to an ext4 NVMe drive.

  • Both libraries wait 1ms before writing a batch (--gun-until 1), and both batch up to 10,000 writes into files of up to 1 MB.

  • Every process ran on the four fast cores, CPUs 0 to 3 (--cpu 0-3), so results don't depend on which cores a run is given.

  • Each figure is the median of 3 runs. Verified counts how many of a sample of the records were read back correctly afterwards, in a fresh process.

Results

Scenario

Holster (writes/s)

Gun (writes/s)

Holster median latency (ms)

Gun median latency (ms)

Holster verified (records)

Gun verified (records)

small-sequential

96

111

10.2

9.2

1001/1001

675/1001

small-concurrent

3,939

6,237

21.8

14.6

1001/1001

984/1001

small-burst

7,932

12,259

122.1

74.4

1001/1001

922/1001

large-1kb-concurrent

6,897

7,135

12.5

12.3

101/101

101/101

many-properties

276

171

3.5

5.6

1/1

0/1

large-1kb

285

237

3.5

3.9

101/101

101/101

large-10kb

247

195

3.8

4.8

51/51

51/51

large-100kb

179

103

4.7

8.0

11/11

11/11

overwrite

309

265

3.2

3.5

101/101

101/101

user-small-sequential

210

128

4.7

7.5

101/101

42/101

user-small-concurrent

1,124

848

81.9

106.8

201/201

194/201

user-overwrite

248

262

4.0

3.6

21/21

21/21

radisk-direct

19,415

9,868

4.9

9.6

3003/3003

2967/3003

Findings

The two are quite similar in many ways, as you would expect since Holster is a fork of an early version of the GunDB code. The reason Holster exists was the missing writes, so they're not unexpected here. The radisk numbers look huge for both Holster and GunDB, but that's because they're writing straight to disk and get to skip all the API overheads of the other tests. The reason why Holster is twice as fast on this benchmark is that it keeps files it has already parsed in memory, whereas GunDB reads and parses each file again before every write.

GunDB is faster for small public records because it uses keys as the ids it stores data under, so records with sequential keys land in the same file. Holster uses random ids, which spread a batch across files. This is possibly something Holster could improve on later.

The most important result for me in the numbers was being able to find areas of Holster to improve, which are now in the 3.0.0 release. Most of the improvements don't make a difference at an application level, but being able to run a server on fewer resources is also an important goal and a big win here.
Returning to signed properties

I've been adding some benchmarking to Holster, which I will share next, but it's led me to review a lot of how Holster works. The thing that stood out most is timestamp signatures, which I switched to as a performance improvement, but which turn out to be fundamentally broken. This has meant returning to signed properties, which can be done in parallel anyway and with some other improvements to how signatures are generated has meant only a small performance cost.

This has required a major release, because servers should no longer accept timestamp signatures on data. Upgraded servers will continue serving existing data, they just won't accept data with old signatures. Browsers will continue to accept data with old signatures, which allows logged in users to write new signatures as they interact with existing data. Any application running Holster needs to update the browser and server versions at the same time so they can continue to exchange data.

Claude continues to find issues and then improve the code base, with many other gaps fixed in this release. This includes passwords now having stronger protection and fixing data encoding issues from user data. Some keywords and special characters previously made it through the code that caused issues for JavaScript and filenames on disk.

Holster Performance Improvements

The great thing about writing a complicated application that relies on Holster being responsive to requests, is that you quickly find where the bottlenecks are. Claude also knows that the two projects are heavily related and is happy to switch between code bases when it find a problem in either. So when I Haza Website started slowing down with lots of pages in a project, it will go looking at the Holster code pretty quickly when looking for a reason.

The Holster 2.3.5 release is the performance improvements it found, with an impressive result that Holster now runs it's test suite in 3.5 seconds, down from nearly 6 seconds (in parallel). This is mostly thanks to removing a retry check, which made sure references to nodes existed before they're used. This was definitely a good check to have, but a concurrency issue fixed in an earlier release inadvertently removed the need for it. It did this by serializing rel creation for the same soul and property.

The retry meant many requests were waiting at least the minimum 50 milliseconds just to be sure it existed, but it was no longer necessary and there are specific tests that show that. I Haza Website has it's own tests and these went from 150 seconds down to under 60 seconds to run the full test suite.

Some other improvements went into this release, such as only responding to a client making a request rather than broadcasting the response to all clients. This reduces wire chatter while allowing actual changes to propagate as expected. Clients already ignore data they haven't asked for so the extra broadcasts weren't being listened for anyway.

Another improvement for browser requests is relaxing the message queue rates when making requests. It was initially designed to prevent overloading both browser CPU and relays that clients request data from, but it can do this while also being responsive to application requests which tend to occur in bursts. Requests can now go out in batches of up to 100, instead of waiting 50 millisecond between each request. Browsers now also check if they're connected to any peers, which means there's no reason to wait before resolving the request when offline.

Self Hosting

Hello! This is like a First Post all over again, this time publishing from i.haza.website! 🎉️

I've held off posting a few updates so that I could finish the changes required to bring this blog over, and that day has finally come. Like with the docs and holster sites, there were a lot of incremental changes to make it happen. I will talk more about them in future posts, for now I'm happy to be writing in a nice editor, that auto saves updates, allows me to create drafts, and has some nice templating features built in.

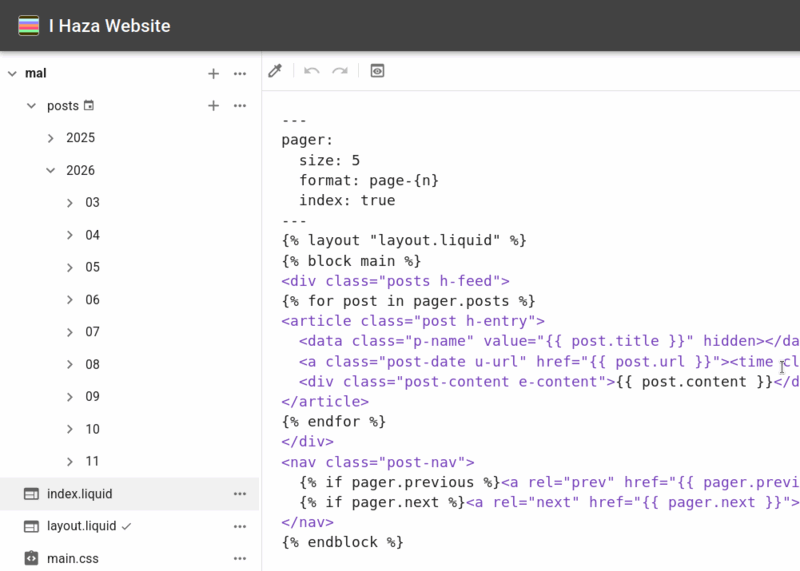
There's quite a few features you need for a static site to publish a blog, one I really wanted from the beginning is multiple posts on the home page. This was added as Front Matter at the start of a template, which makes it capable of publishing pages that don't otherwise exist in your folder structure:

holster.haza.website

The Holster website has been gone since rebuilding i.haza.website, it's now back as a replacement for the github wiki docs with updated information for all API's and better examples 🎉

I Haza Website also got some updates as I was working on this, so it now does nice preview navigation while you're editing pages. You can start from one page in preview mode, navigate to another page you're working on and continue editing from there.

There's also a lot of code examples on the site so I added a Copy Code plugin that allows you to copy code blocks if you want to run them interactively in Node. There's also a theme switcher plugin for light and dark mode: